
Ryan
IP Proxy Research Team
Ryan is a web data and proxy infrastructure specialist focused on IP networks, scraping systems, SERP APIs, and global data access solutions. He shares practical insights on proxy usage, data collection architecture, and scalable web intelligence systems.
Ryan's Articles
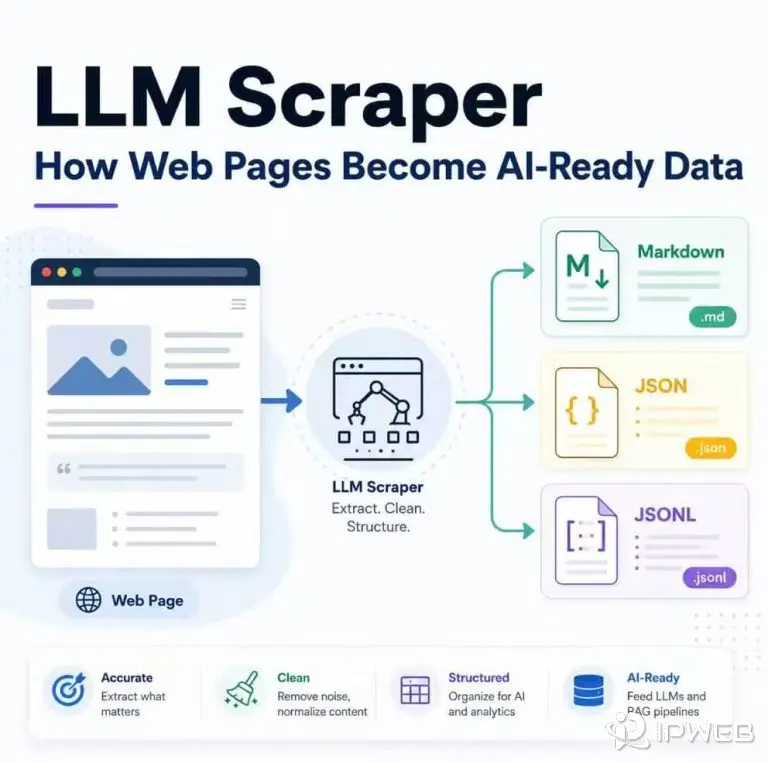
LLM Scraper: How Web Pages Become AI-Ready Data
Raw web pages are rarely ready for retrieval-augmented generation, structured extraction, or model evaluation. Navigation, cookie banners, repeated templates, JavaScript-loaded content, missing metadata, and inconsistent page structures all create noise before the content reaches an AI system. An LLM scraper addresses that gap. The term is informal rather than a standardized protocol, and it commonly describes either an LLM-powered extraction tool or a web-content pipeline that prepares source-grounded data for downstream large language model applications. Direct Answer An LLM scraper collects web content and transforms it into cleaner, structured input for AI workflows. Some implementations use an LLM to identify...
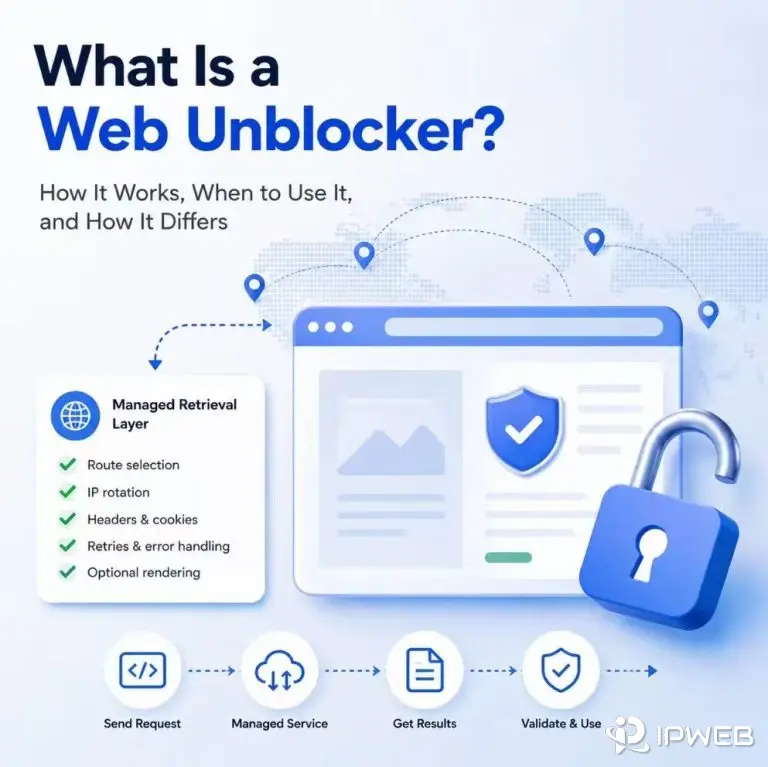
What Is a Web Unblocker? How It Differs From a Proxy
A web unblocker is a managed request-delivery layer that sits between your application and a target URL. Instead of maintaining every routing, retry, response-checking, and optional rendering step yourself, you send the target through one hosted endpoint and receive page content or another supported output. The practical difference from a standard proxy server is ownership of the workflow: a proxy mainly changes the network route, while a web unblocker manages more of request delivery. Your application still owns target selection, parsing, validation, and downstream data use. Quick Answer A web unblocker combines proxy routing with managed delivery tasks such as...
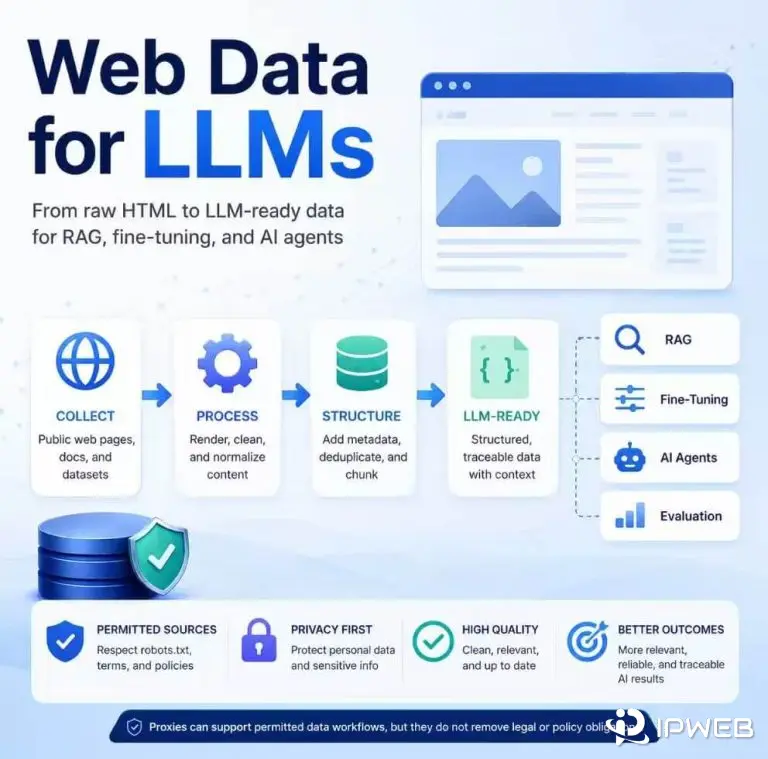
How Web Content Feeds RAG and AI Models
LLMs do not become useful for current business questions just because someone gives them a pile of web pages. Raw HTML is noisy. Search results change. JavaScript pages may hide the content until a browser renders them. Documents need metadata, deduplication, chunking, and refresh rules before they can support a reliable AI workflow. This guide explains what LLM data means, how public web content becomes AI-ready, how RAG differs from fine-tuning, and what to check before using an LLM scraper or web data platform. Direct Answer LLM data is the text, metadata, documents, examples, and structured records used to train,...
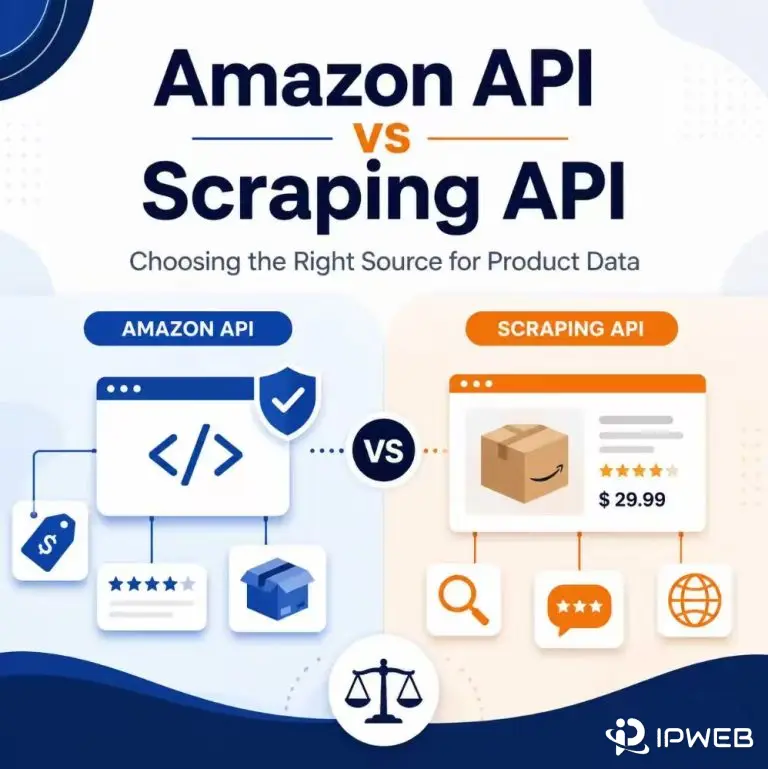
Amazon Product API vs Scraping API for Product Data
"Amazon Product API" is a broad search phrase rather than the name of one current Amazon interface. Amazon product data may come from the Creators API, Selling Partner API (SP-API), approved feeds, permitted public-page checks, or manual validation. The right source depends on who is requesting the data, which fields are needed, and what the data will support. Direct Answer Use the Amazon Creators API for approved affiliate and publisher product-discovery workflows. Use SP-API for authorized seller or vendor catalog, pricing, and customer-feedback operations. Use a scraping API only for permitted public-page validation when the official interface does not provide...
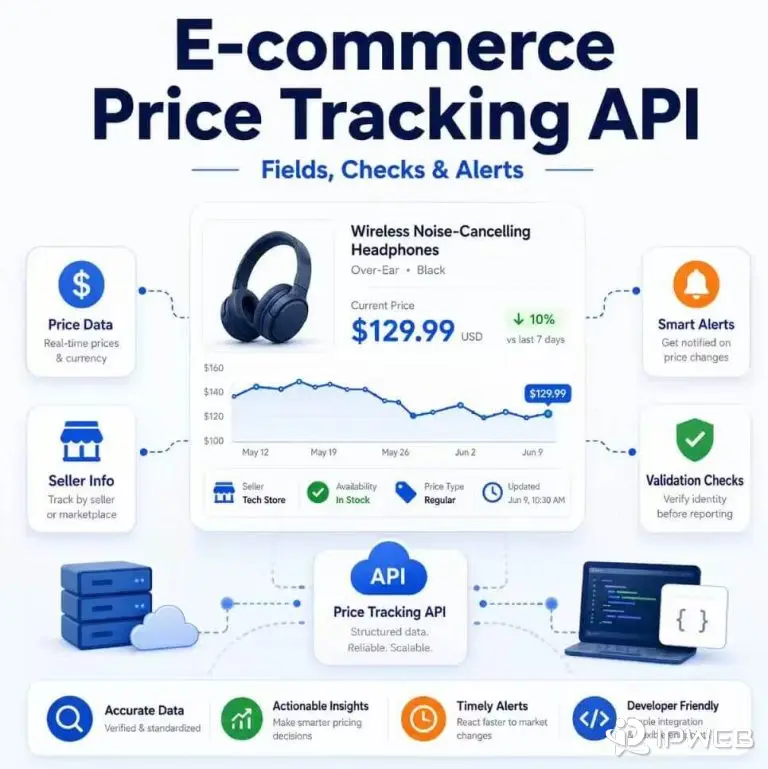
E-commerce Price Tracking API: What to Check
Price tracking sounds simple until the same product has multiple sellers, variants, discounts, shipping rules, currency formats, coupon states, and regional availability. A useful price tracking API does more than return a number. It preserves enough context to explain exactly what was observed. Direct Answer An e-commerce price tracking API should return product identity, canonical URL, price, currency, seller, availability, shipping context, promotion state, timestamp, and source metadata. Reliable tracking also requires validating that each price belongs to the correct product variant, seller, region, and page state. Key Takeaways A price without product, seller, region, currency, and timestamp context is...
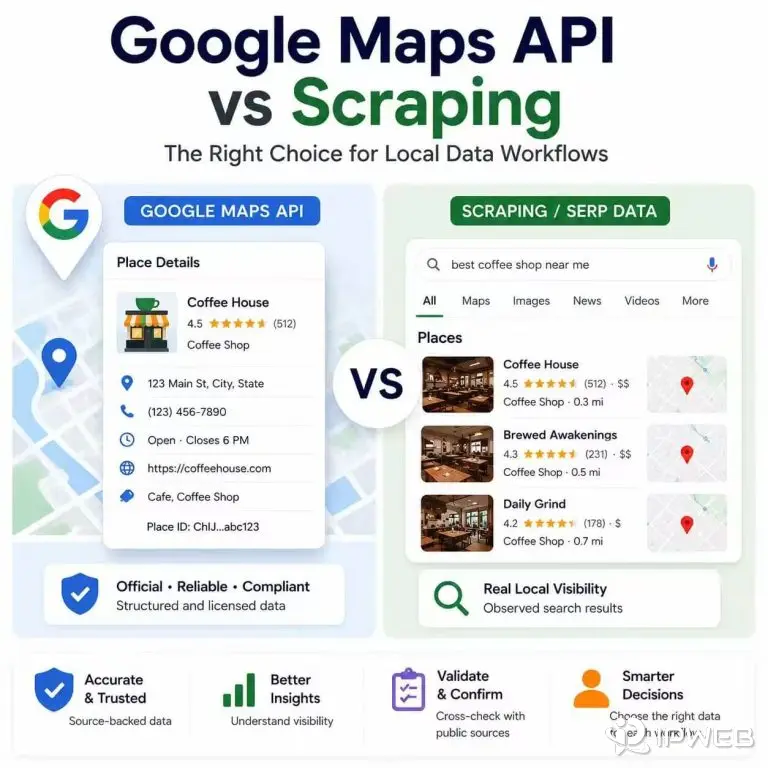
Google Maps API vs Scraping: Which Should You Use?
Local data projects often begin with a simple request: find businesses, verify addresses, compare listings, or track local search visibility. The difficult part is choosing the right source. Google Maps Platform APIs, local SERP data, public business pages, and manual checks can all support local-data work, but they answer different questions. Direct Answer Use Google Maps Platform APIs when you need documented place, geocoding, routing, autocomplete, or map functions inside an application. Use local SERP data when you need to observe how local results appear for a specific query, location, language, or device. Use public-page checks only for permitted validation...
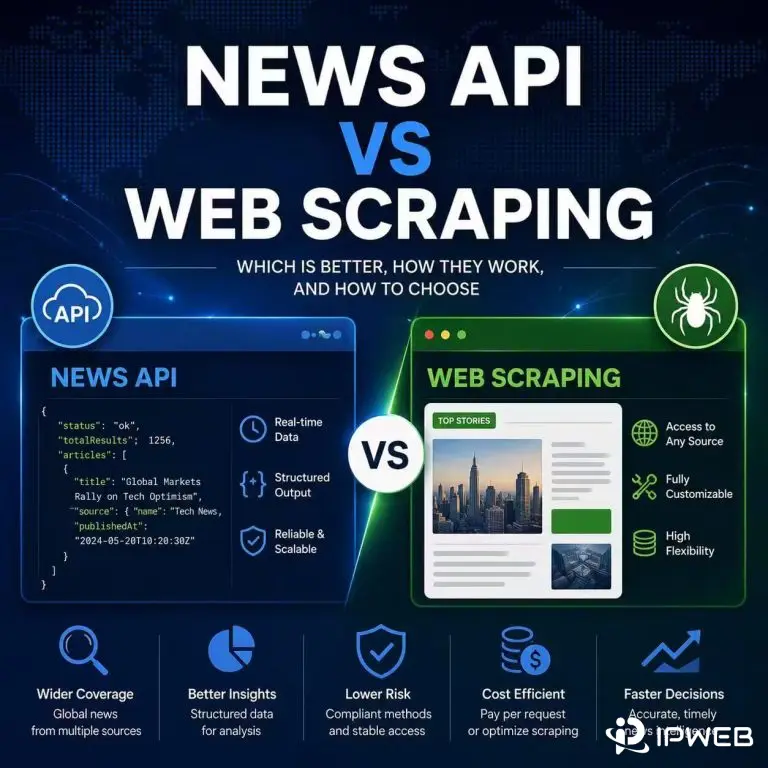
News API vs Web Scraping: Which Should You Use?
News data can support brand monitoring, market research, event alerts, competitive analysis, and AI summaries. The difficult part is not collecting more records. It is choosing a source that provides the coverage, context, freshness, and usage rights your workflow actually needs. Direct Answer Choose a news API when you need structured records, predictable request handling, and broad source coverage with less maintenance. Choose web scraping when permitted public pages contain niche sources, page-level context, or fields the API does not provide. RSS feeds and licensed datasets may be better when the publisher already offers an official feed or when licensing...
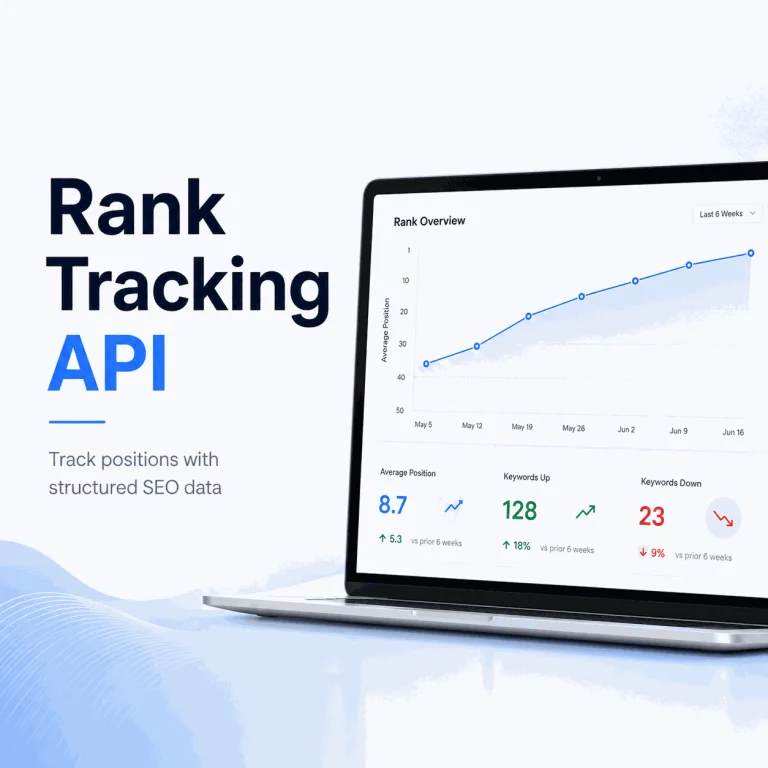
Rank Tracking API: Workflow, Data, and Validation
Rank tracking becomes messy when teams move beyond a few manual keyword checks. One person may search from a desktop in one city, another from a phone in another country, and a reporting system may need the same queries every day. A rank tracking API gives teams a repeatable way to collect and compare ranking snapshots. Direct AnswerA rank tracking API is an interface for collecting keyword position data on a schedule. It sends configured search queries, locations, languages, devices, and search engines to a ranking data provider, then returns structured results that can be stored, compared, and reported over...
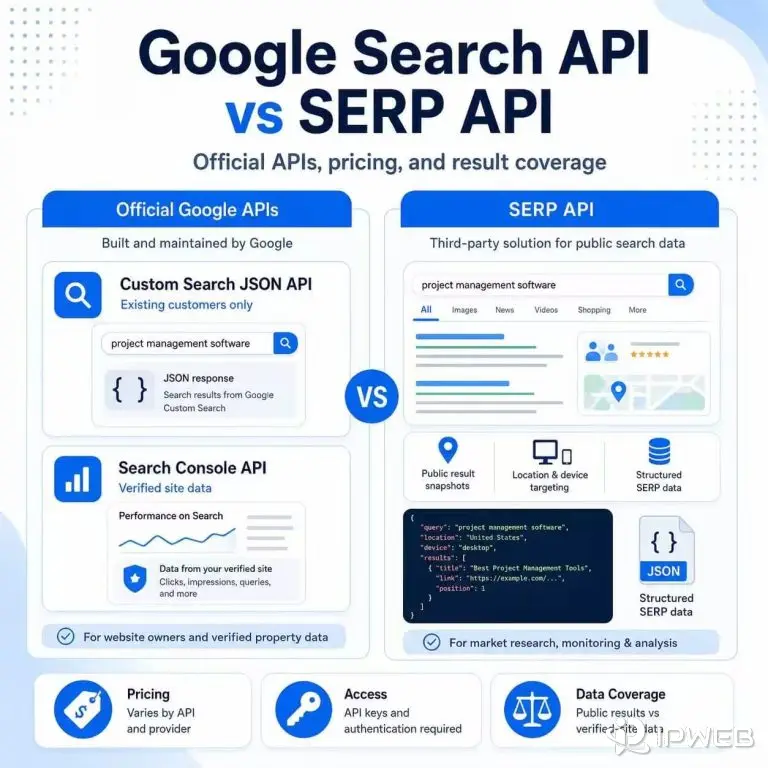
Google Search API vs SERP API: Which to Use
Searching for a “Google Search API” can lead to several different products. You may need search inside a website, performance data for a verified property, or structured snapshots of public Google results. These tools do not return the same data, and choosing the wrong one can create gaps in coverage, pricing, or implementation. There is also an important 2026 change: Google’s Custom Search JSON API is closed to new customers. Existing customers have until January 1, 2027 to move to another solution. That makes the intended data source—not the broad keyword “Google Search API”—the correct starting point for a new...
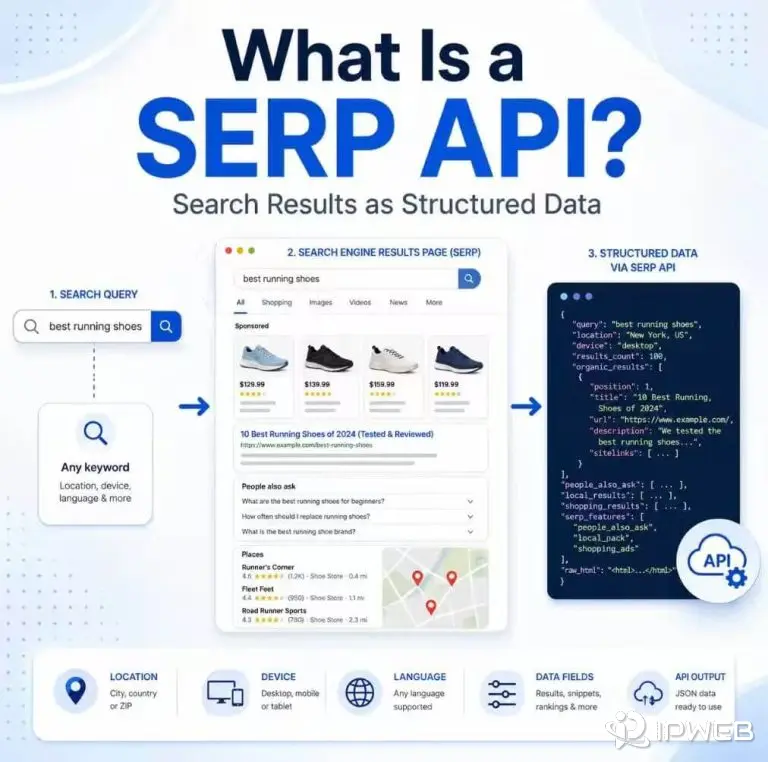
What Is a SERP API?
SERP data looks simple from a browser: type a query, get a search results page, read the links. At workflow scale, it becomes harder. Results can vary by country, language, device, location, personalization signals, search features, ads, local packs, and freshness. A SERP API exists to make that search-result collection process more predictable for applications. Direct AnswerA SERP API is an interface that returns structured search engine results for a query, location, language, device, or search type. It can help with SEO monitoring, AI grounding, market research, and regional QA, but it does not guarantee ranking accuracy, remove search-engine policy...
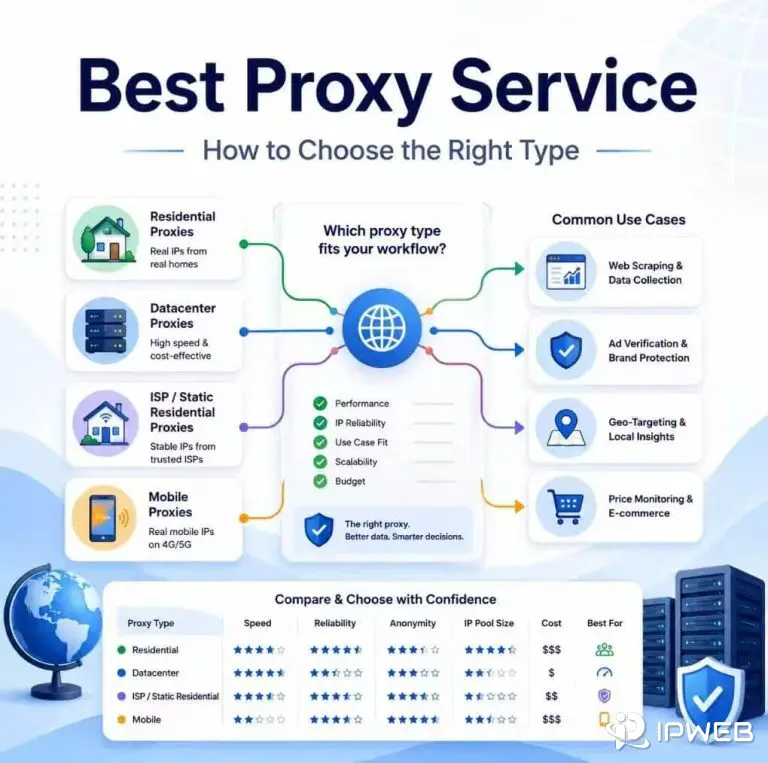
How to Choose the Best Proxy Service for Web Data
Choosing the wrong proxy type can waste budget before a workflow even starts. Some teams pay for rotating residential traffic when one stable datacenter IP would be enough. Others use datacenter routes for location-sensitive testing and then spend hours troubleshooting inconsistent results. The best proxy service is not automatically the provider with the largest IP pool or the lowest advertised price. It is the service whose proxy type, location controls, session behavior, authentication, and pricing model match the work you actually need to run. For regional QA, public web data workflows, backend checks, and authorized testing, ask which setup offers...
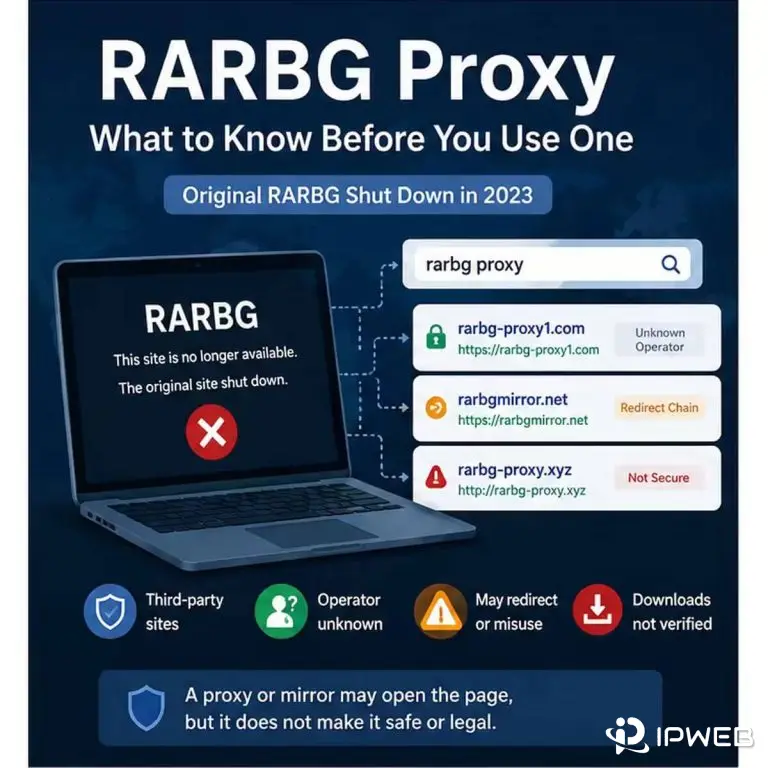
RARBG Proxy: What to Know Before You Use One
Search for a RARBG proxy today and you will find pages that look familiar but are not the original service. RARBG closed in May 2023, so current results are generally third-party mirrors, clone sites, web proxy pages, or link lists operated by unrelated parties. This guide does not publish a live RARBG proxy list. Instead, it explains what the term means, why these pages change so often, how a mirror differs from a proxy server, and which trust and network signals to check before relying on any result. Direct Answer A RARBG proxy is a broad label for a third-party...