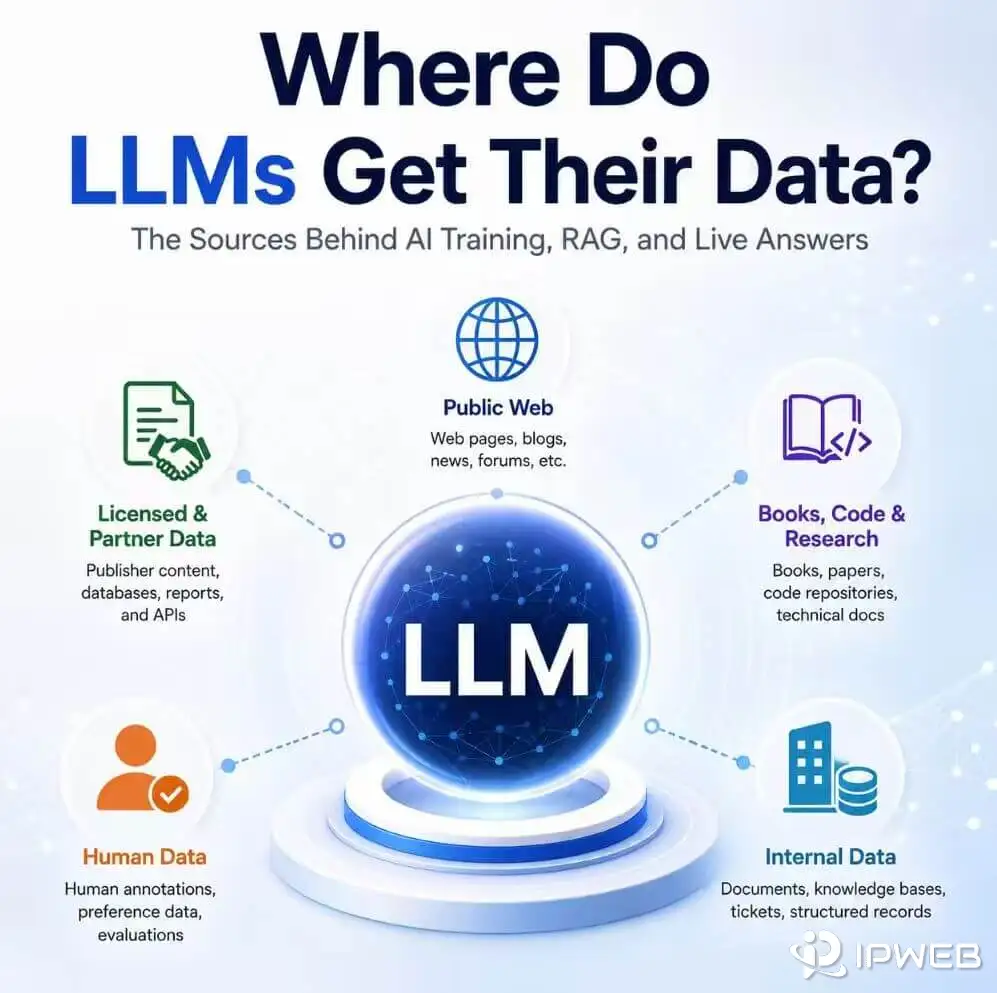
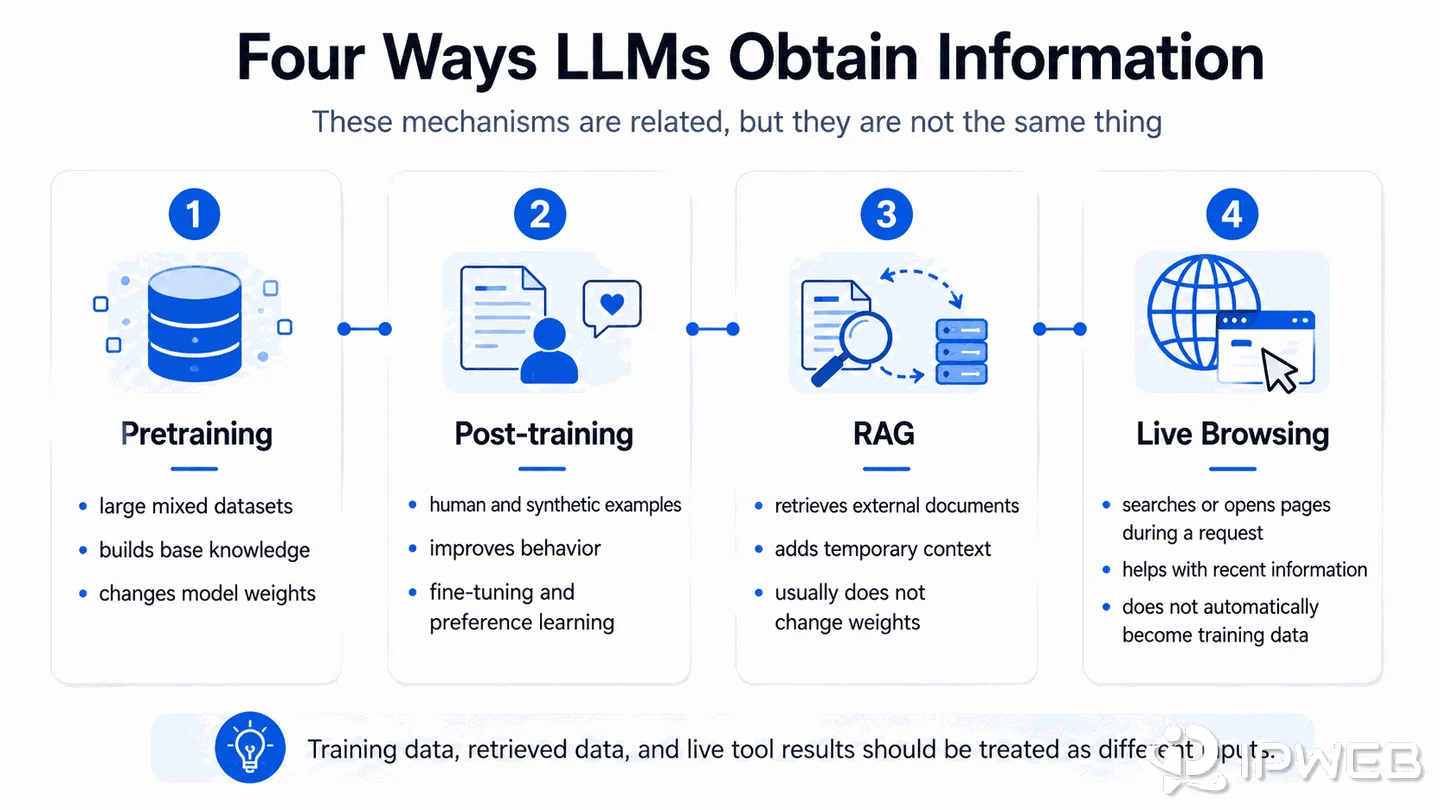
When people ask where large language models get their data, they may be referring to several different processes. A foundation model learns broad language patterns during pretraining, an assistant is refined during post-training, a RAG application retrieves documents at request time, and some products can use search or browsing tools to access current information.
These mechanisms are related, but they are not interchangeable. A document retrieved by a RAG system is not automatically added to the model's training data, and a model that can browse the web is not continuously retraining itself on every page it opens.
LLM training data usually comes from six broad source categories: public web content; licensed or partner data; books, research, code, and technical documentation; human-created examples; synthetic data; and user data permitted for training. After training, an LLM can also receive current or private information through RAG, search, browsing, or connected tools. Those runtime sources provide context for a request but do not automatically become training data.
- Training data, retrieved documents, and live web results are different sources of model knowledge.
- Pretraining builds broad capabilities, while post-training shapes task performance, safety, and assistant behavior.
- Publicly accessible content may be part of a training mix, but public visibility does not remove copyright, privacy, contractual, or other legal considerations.
- Model providers usually describe source categories rather than publishing a complete item-by-item list of every training record.
- There is no single universal LLM data repository used by every model; providers assemble different mixtures and may use curated public datasets such as web-crawl corpora.
- Private company documents are commonly used through RAG or controlled customization, not automatically absorbed into a public foundation model.
What “Get Their Data” Actually Means
An LLM can receive information at different stages of its lifecycle. The stage matters because it determines whether the information changes the model's parameters, temporarily appears in the prompt, or is fetched only for one response.
| Mechanism | When It Happens | Typical Data | Does It Change Model Weights? |
|---|---|---|---|
| Pretraining | Before general model release | Large collections of public, licensed, partner, human-created, and synthetic data | Yes |
| Post-training | After pretraining and before or between releases | Instructions, demonstrations, preference data, safety examples, and evaluations | Usually yes |
| RAG or retrieval | When a user submits a request | Relevant passages from documents, databases, or knowledge bases | No |
| Search or browsing tools | During a tool-enabled request | Current search results, webpages, or connected sources | No |
In short: pretraining and post-training can change the model, while RAG and browsing provide temporary information at request time without automatically rewriting the model weights.
Pretraining teaches a model statistical patterns across language, code, images, audio, or other supported modalities. Post-training then improves how the model follows instructions, handles safety constraints, completes specific tasks, or expresses preferences. By contrast, RAG and browsing add temporary context without rewriting the base model.
Where Do LLMs Get Their Training Data?
There is no universal dataset used by every LLM. Each provider selects its own combination of sources, filters, licenses, exclusions, and post-training material. Even two versions from the same provider may use different collection dates, data mixtures, or training methods.
| Source Category | Examples | Typical Contribution | Main Limitation |
|---|---|---|---|
| Public web content | Open webpages, forums, blogs, documentation, and public posts | Breadth of language, topics, styles, and current-era knowledge | Variable quality, duplication, rights, privacy, and provenance |
| Licensed or partner data | Publisher archives, commercial collections, specialist databases, and private partnerships | Domain coverage and clearer contractual access | License scope, cost, and uneven availability |
| Books, research, code, and documentation | Literary text, papers, manuals, repositories, and technical references | Long-form reasoning, specialist language, and technical patterns | Versioning, copyright, licensing, and contamination risks |
| Human-created data | Demonstrations, labels, rankings, red-team examples, and evaluations | Instruction following, safety, preference learning, and task performance | Cost, annotator consistency, and coverage gaps |
| Synthetic data | Model-generated prompts, answers, critiques, conversations, or edge cases | Targeted coverage, multilingual examples, and rare scenarios | Error reinforcement and reduced diversity if poorly validated |
| Permitted user data | Interactions or feedback included under a provider's stated settings and policies | Real-world usage patterns and product improvement | Privacy, consent, product-specific controls, and policy differences |
The main training-data sources are: public web content, licensed or partner data, books/research/code/documentation, human-created examples, synthetic data, and permitted user data.
Public Web Data
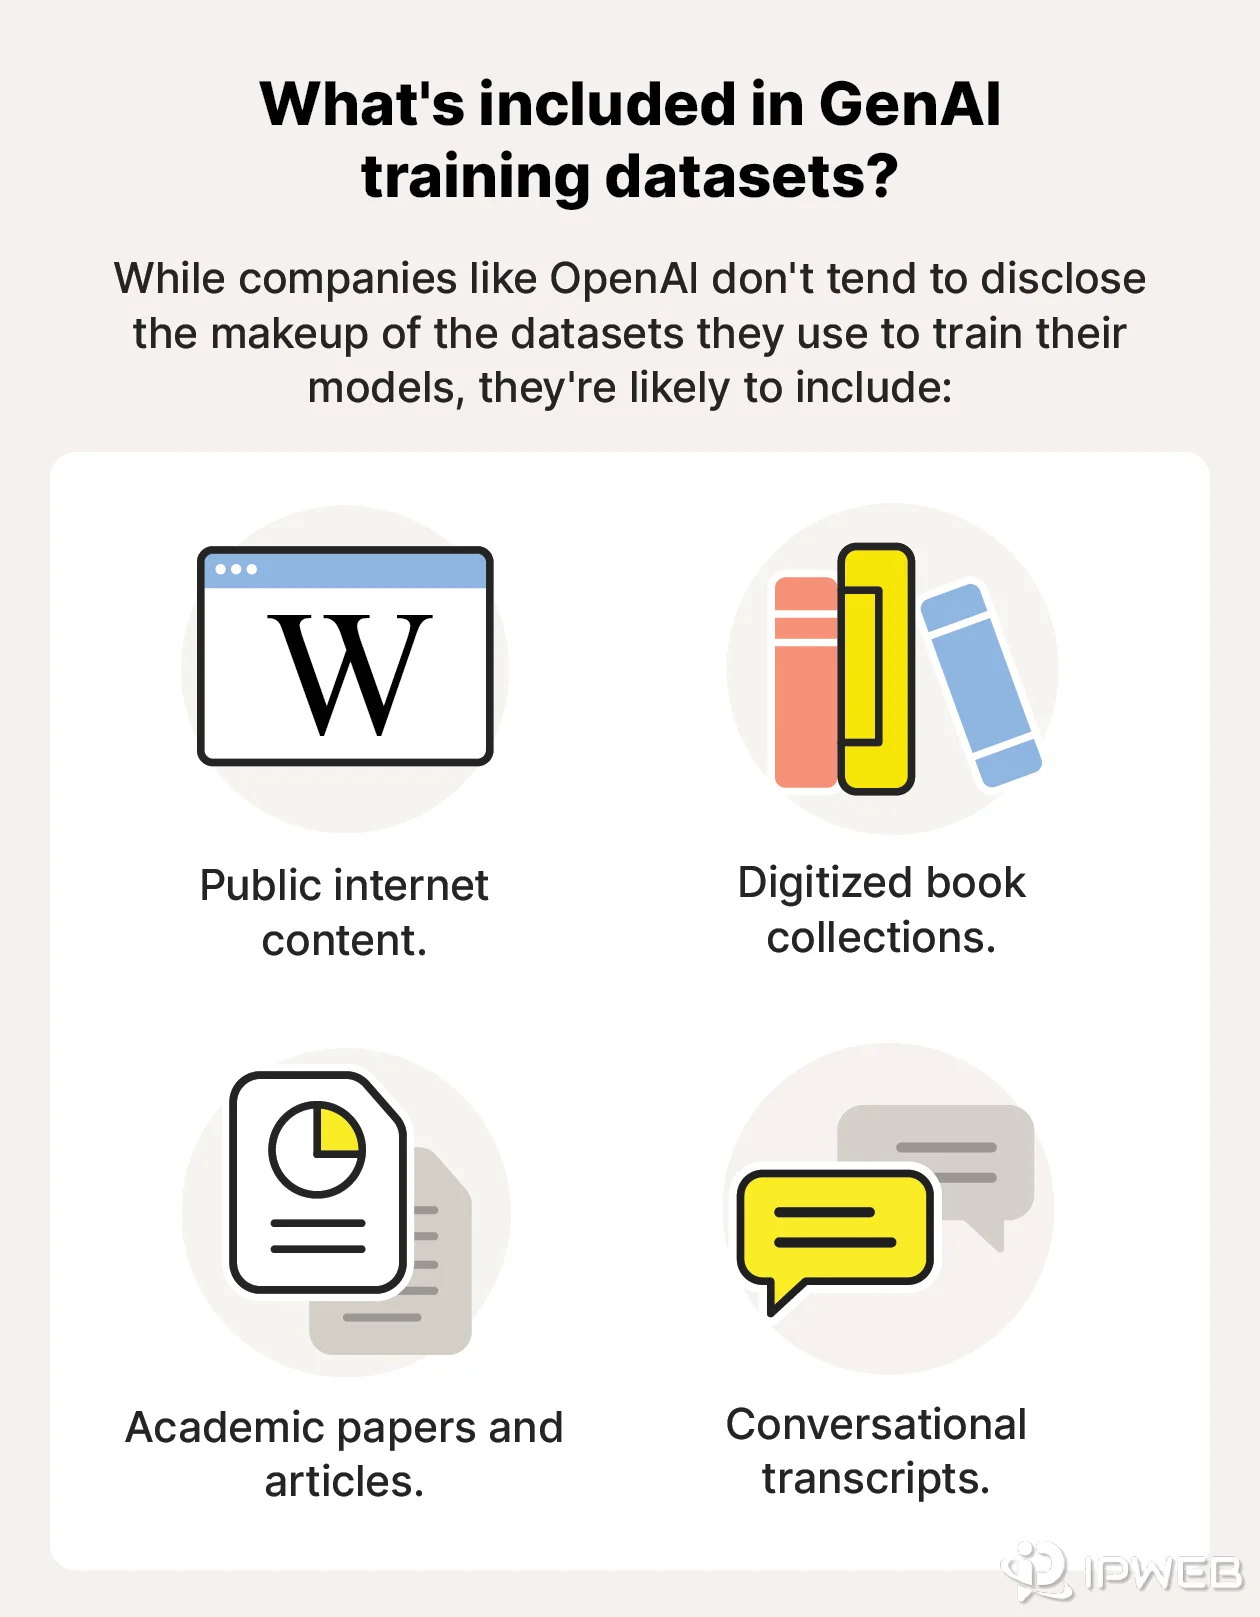
Public web content can give a model broad exposure to natural language, technical explanations, discussions, cultural references, and many writing styles. Depending on the provider, this category may include openly accessible webpages, public forums, blogs, documentation, public posts, and other material available without authentication.
For example, OpenAI's description of foundation-model development identifies publicly available internet information as one of several source categories, alongside third-party partnerships and information provided or generated by users, trainers, and researchers. It also describes filtering and controls that affect what is collected or retained.
However, a page being visible in a browser does not answer every question about permitted reuse. Copyright, privacy, database rights, contractual terms, jurisdiction, and the purpose of collection can all matter. The U.S. Copyright Office's AI initiative treats the use of copyrighted works in generative AI training as a substantive legal and policy issue rather than assuming that public access settles the matter.
Public web content is also noisy. A raw crawl may contain duplicate pages, copied articles, spam, outdated documentation, navigation templates, machine-generated pages, or personal information. Providers therefore apply selection, filtering, classification, and deduplication before using source material in a training process. Those preparation steps affect what the model ultimately learns, but they are separate from the question of where the source material originated.
Large web archives are rarely useful as raw training input. Common Crawl, for example, maintains a large open repository of web crawl data. Curated datasets can then be built from such archives: Hugging Face's FineWeb dataset documents filtering and deduplication steps used to turn Common Crawl data into a cleaner English pretraining corpus.
For a practical look at how retrieved webpages are cleaned, normalized, chunked, and preserved with source metadata before entering AI workflows, see IPWeb's LLM scraper guide. It covers the preparation layer between raw pages and downstream RAG, evaluation, or model-training data.
For teams building permitted public-web datasets across multiple regions, dynamic residential proxies can provide location-selectable network routes for an existing crawler or data pipeline. The proxy handles the network route; the data team still owns source selection, permission review, filtering, deduplication, provenance, and dataset quality.
Do LLMs Use a Specific Data Repository?
No single data repository is used by every LLM. Each developer builds a model-specific training mixture from sources it can access and is permitted to use. Those mixtures may include large public web archives, curated open datasets, licensed collections, internally created examples, synthetic data, and proprietary sources.
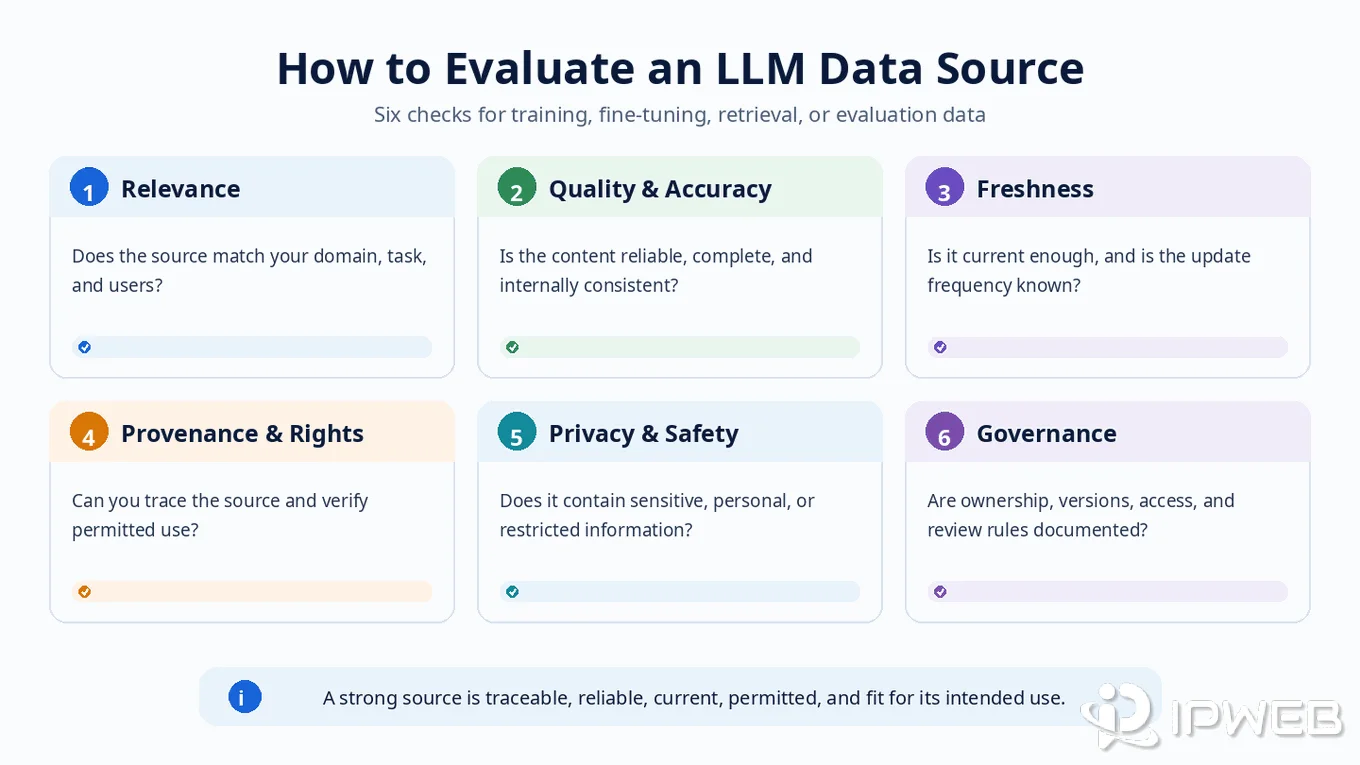
Common Crawl is one example of an open web-data repository, while FineWeb is an example of a curated pretraining dataset derived from Common Crawl. Other datasets may be hosted on research repositories or platforms such as Kaggle, but a public download does not automatically make a dataset suitable for model training. Check provenance, licensing, freshness, schema, duplication, and refreshability before use; IPWeb's guide on evaluating Kaggle datasets provides a practical checklist.
The important distinction is that a repository is a source or storage location, not a universal LLM knowledge base. Providers still choose, filter, transform, combine, and govern data before it becomes part of a training run.
Licensed, Partner, and Publisher Data
Some LLM developers use datasets obtained through commercial agreements, publisher relationships, research partnerships, or other third-party arrangements. These sources may provide specialist coverage, archives, multilingual material, metadata, images, audio, video, or information that is not freely available on the public web.
Licensed access can offer clearer contractual terms, but it does not mean every model has access to the same books, publications, or databases. Agreements differ by provider, territory, content type, permitted use, and time period. A provider may also disclose that it uses partner data without publishing the identity of every source or every record included in a model version.
Teams that use pre-built or custom datasets should verify the available fields, provenance, update schedule, licensing terms, and permitted uses before applying the data to training, evaluation, or research. A dataset being packaged for AI use does not by itself establish quality or permission.
Books, academic papers, code repositories, and technical documentation may appear through public sources, licensed collections, open licenses, direct partnerships, or a mixture of those routes. Because these categories can overlap, it is more accurate to ask how a provider obtained and governed a source than to assume that every book, code sample, or research paper entered the training mix in the same way.
Human-Labeled and Synthetic Data
Large volumes of broad text can help a model learn language, but they do not automatically produce a useful assistant. Post-training often relies on more targeted examples created, reviewed, ranked, or labeled by people. These may include ideal responses, comparisons between outputs, safety scenarios, refusal examples, domain evaluations, and demonstrations of how to complete a task.
Human feedback can improve instruction following and align behavior with product goals, but it is not perfectly neutral. Annotation guidelines, cultural assumptions, reviewer expertise, and task design can influence the resulting model. High-quality evaluation data is therefore important for checking whether post-training improved one behavior while weakening another.
Synthetic data is generated with models or rule-based systems rather than collected directly from human-authored sources. It can expand rare scenarios, create multilingual examples, test edge cases, or provide structured practice data. It is useful when carefully validated, but repeated training on low-quality synthetic outputs can reproduce errors, narrow linguistic variety, or amplify assumptions already present in the generating model.
Training Data vs RAG vs Live Browsing
Training changes a model's parameters. RAG does not. In a retrieval-augmented generation workflow, a system searches a document collection after the model has been trained, adds relevant passages to the prompt, and asks the model to answer from that temporary context. In practical terms, training changes model behavior or internal parameters, while RAG supplies external information at request time. For a detailed comparison of how retrieval data differs from model-training data, see IPWeb's RAG vs fine-tuning guide.
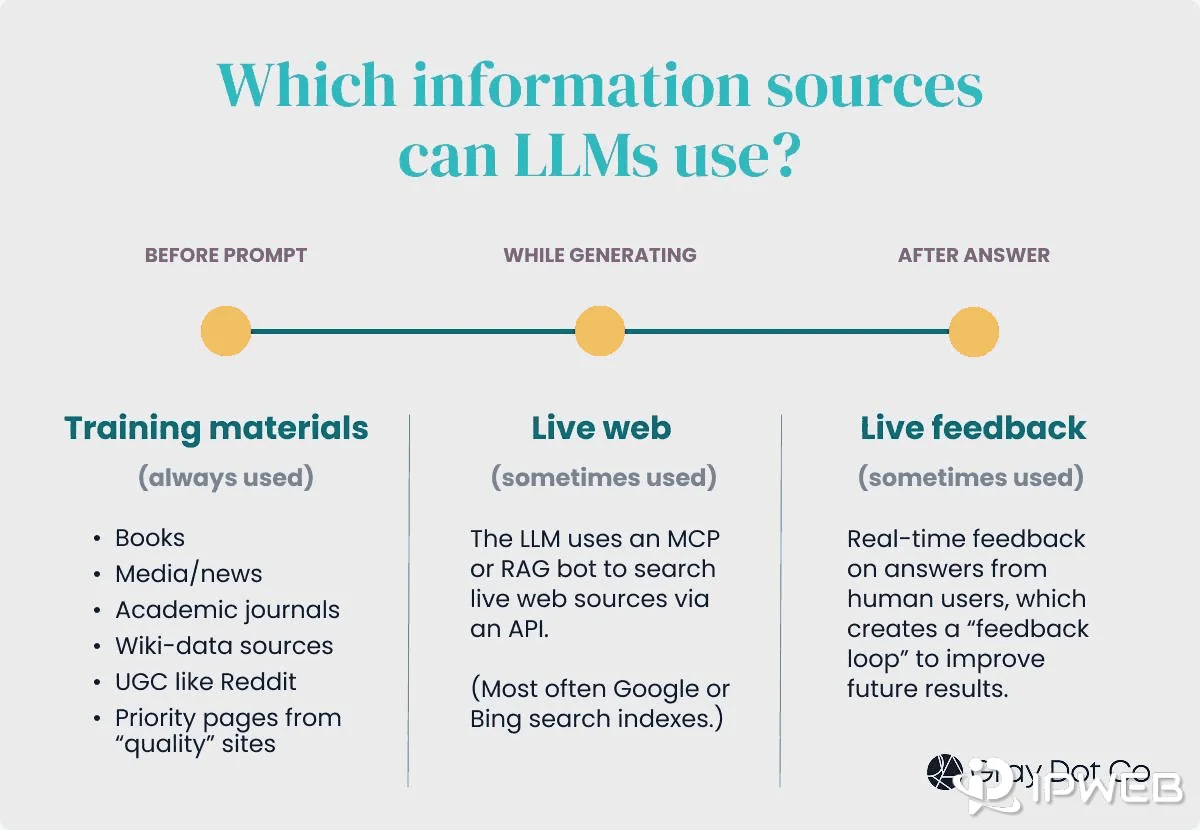
This distinction explains how a company can use internal policies, support records, product documentation, or research notes without training a new foundation model. The documents remain in a controlled external store and are retrieved only when relevant. Access controls still matter: a user should not receive a passage from a document they are not authorized to open.
Live search and browsing are another separate layer. A tool-enabled model may search for recent information or open a webpage during a request. That result can support the current response, but it does not mean the page is immediately incorporated into the model's weights. A later training process would require separate collection, selection, governance, and model-development decisions.
For a deeper explanation of cleaning, structuring, metadata, and validation before AI ingestion, see IPWeb's guide to LLM-ready data. That topic covers data preparation; this article focuses on source categories and information mechanisms.
Do Providers Reveal Their Full Training Datasets?
Most major providers publish categories, cutoff dates, system cards, transparency reports, or examples of training methods rather than a complete inventory of every URL, book, image, code file, conversation, or dataset used in a model version. Several practical reasons contribute to this: training mixtures can contain enormous numbers of records, third-party agreements may restrict disclosure, and developers may treat parts of their data pipeline as proprietary.
Disclosure also varies by model. Anthropic's model reports, for example, describe categories such as publicly available internet information, public or private datasets, contractor or user-permitted data, and internally generated or synthetic data for particular Claude versions. The exact categories and cutoff dates can change across releases.
Because disclosures are model-specific, claims such as “all LLMs are trained on the entire internet” or “this provider trained on this exact website” are usually too broad unless supported by direct evidence. A safer conclusion is that public web content is one possible source category among several, and the presence of a category does not prove that any individual page was included.
Are Private Business Documents Used to Train LLMs?
Private company documents are not automatically part of a public model's original training dataset. In business applications, they are often connected through RAG, added to a controlled fine-tuning project, or supplied in a prompt under the provider's enterprise or API data terms.
Whether prompts, outputs, uploaded files, or feedback may be used for broader model improvement depends on the provider, product tier, account settings, and explicit data controls. Consumer and business products can follow different defaults. Teams should therefore review the current policy for the exact service they use rather than applying one general assumption to every AI product.
For sensitive data, the practical questions are not only whether the model “learns” the document. Teams should also check retention, logging, access permissions, regional processing, deletion controls, encryption, and whether a human reviewer or third-party subsystem can access the content.
Frequently Asked Questions
Final Thoughts
LLMs do not get all of their information through one pipeline. Broad capabilities usually begin with pretraining, assistant behavior is shaped during post-training, private or current information can be supplied through retrieval, and live tools can fetch information for an individual request.
Understanding those boundaries prevents several common mistakes: assuming that a retrieved document retrains the model, assuming that a browsing feature has no knowledge cutoff, or assuming that public availability proves a specific page was included in training. The most reliable answer is always model- and product-specific: check the provider's current disclosures, system cards, and data controls before drawing conclusions about a particular LLM.
If you are building a permitted public-web data workflow and want to validate network routing before scaling collection, IPWeb also offers a 1GB, 24-hour proxy trial so you can test the route in your own crawler or application first.